The AI Recommendation Consistency Audit: A Testing Framework for Ecommerce Brands
A reproducible framework for measuring how often products appear in AI shopping recommendations—and how results change across repeated runs, prompts, platforms, accounts, and markets.
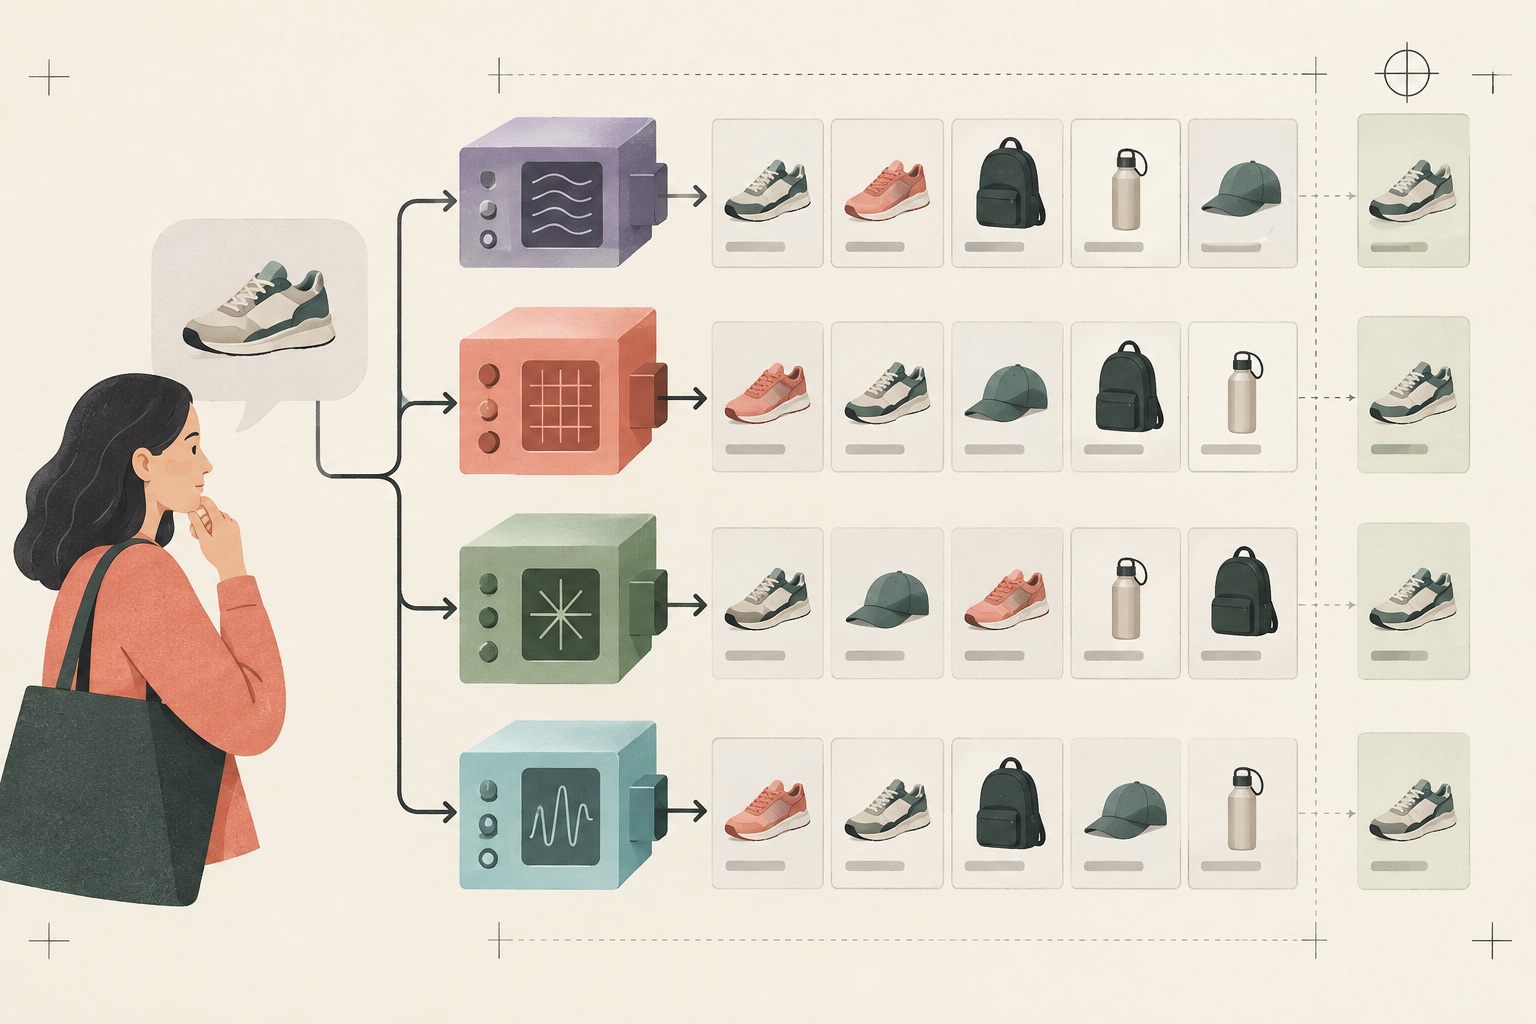
Ask an AI shopping assistant to recommend a product once and you may see your brand. Ask the same question again and it may disappear. Change one phrase, use a different account, or run the query from another market and the shortlist can change again.
That does not make AI shopping visibility meaningless. It makes it probabilistic. The useful question is no longer, "Did we appear?" It is, "How often do we appear, under which buying conditions, with what evidence, and how much does the result move when the context changes?"
This guide provides a reproducible AI recommendation consistency audit for ecommerce brands. It is designed for marketing, SEO/GEO, merchandising, product data, and analytics teams that need a defensible baseline rather than a folder of favorable screenshots.
Short Answer
Run the same set of realistic shopping prompts repeatedly across multiple assistants, prompt phrasings, account states, and relevant markets. Record product inclusion, rank, factual accuracy, cited evidence, and constraint compliance. Report rates with confidence intervals, separate stable wins from context-dependent appearances, and change one controllable input at a time before retesting.
Why one AI shopping query proves almost nothing
Traditional search trained teams to think in positions: a page ranks third, an ad occupies the first slot, or a product appears in a carousel. Generative shopping interfaces are less fixed. They may retrieve different sources, construct different consideration sets, interpret vague needs differently, or sample a different answer even when the visible prompt is unchanged.
A 2026 Wharton Generative AI Labs study makes the problem concrete. Researchers ran roughly 26,000 tests across six frontier models and found that recommendations were relatively stable when agents saw only an eight-product grid. Once the researchers added realistic context—a review, several competing sources, a different source order, an injected memory, or a different tool-calling structure—the final choices became less predictable. In one condition, a single source shifted one model's product choice by about 99 percentage points. The lesson for brands is not that measurement is impossible. It is that clean, one-shot tests systematically understate the role of context.
Other research highlights a second problem: an answer can be consistent and still be wrong. ShoppingComp evaluated shopping agents on real-product retrieval, report quality, and safety-critical decisions. Its benchmark found substantial gaps in retrieval and safety, including susceptibility to promotional misinformation. A consistency audit therefore needs two axes: repeatability and quality. Repeating the same unsupported claim ten times is not success.
| Weak measurement | What it misses | Better measurement |
|---|---|---|
| One prompt, run once | Sampling variation and transient retrieval | Repeated runs of a frozen prompt |
| One assistant | Platform-specific retrieval, data, and ranking | A fixed panel of relevant assistants |
| One generic query | Different customer intents and constraints | A prompt family based on real buying jobs |
| Brand mention only | Rank, product specificity, evidence, and accuracy | A structured output-level scorecard |
| Best screenshot | Failure rate and volatility | All runs, preserved with timestamps |
What the audit should answer
A good recommendation consistency audit is not an attempt to reverse-engineer a model's hidden ranking algorithm. It is an observational test of the customer-facing outcome. It should answer six operational questions:
- Eligibility: Does the brand or product enter the recommended set at all?
- Prominence: When included, is it the first choice, a secondary option, or a passing mention?
- Stability: Does it recur when the exact condition is repeated?
- Sensitivity: How much does visibility change with prompt wording, account context, geography, or platform?
- Validity: Does the recommendation actually satisfy the shopper's stated constraints, and are its factual claims correct?
- Traceability: What pages, feeds, citations, or product facts appear to support the answer?
The audit should produce a baseline that can be rerun after a catalog, content, feed, policy, or digital PR change. It should not promise causal certainty from an uncontrolled live system. Platforms update models and retrieval layers without notice, so the goal is decision-grade evidence, not laboratory permanence.
The five dimensions of a defensible test
| Dimension | What to vary | What it reveals |
|---|---|---|
| Assistant or model | Three to five shopping surfaces customers actually use | Whether visibility is portable or platform-dependent |
| Repeated run | Identical prompt, account state, location, and time window | Randomness and retrieval volatility within a condition |
| Prompt phrasing | Semantically equivalent versions plus distinct buying intents | Dependence on vocabulary, specificity, and framing |
| Account context | Signed-out/clean session and a documented signed-in profile, where permitted | Effects of memory, history, and personalization |
| Geography | Real operating markets with controlled locale and delivery destination | Availability, currency, retailer, and regional-source effects |
Time is a sixth dimension that should be held still during a test and varied deliberately between waves. Complete each comparison block in a narrow window—ideally the same day—then repeat the full audit monthly or after a meaningful change. Otherwise, a model update, inventory change, sale, or newly indexed article can be mistaken for the effect you intended to test.
Step 1: Define the decision before collecting answers
Begin with a written test charter. Select the market, category, products, competitors, assistants, and decision the audit will support. A useful first audit covers one product category and 12 to 20 prompts. Do not begin with the whole catalog.
Select representative products
- Revenue leader: the product the business most expects to see.
- Strategic growth product: an item the brand wants to establish.
- Long-tail specialist: a product suited to a narrow need.
- Challenger product: a strong competitor with similar specifications.
- Negative control: your own product that should not qualify for a specific prompt because it violates a hard constraint.
The negative control is important. If an assistant recommends a non-waterproof product for a prompt requiring waterproofing, a brand mention should not be recorded as a win. It is evidence of poor constraint handling.
Write a falsifiable hypothesis
Replace a broad goal such as "improve AI visibility" with something measurable:
Example Hypothesis
For US-based, non-personalized queries asking for a fragrance-free mineral sunscreen under $30, Product A will appear in at least 40% of valid runs across the selected assistant panel, satisfy every hard constraint when recommended, and show no prompt-variant inclusion gap larger than 25 percentage points.
This statement defines the audience, task, threshold, quality condition, and acceptable sensitivity. It can be supported or contradicted by the results.
Step 2: Build a prompt family from real buying jobs
Do not create 20 cosmetic rewrites of "best product." Build prompts around distinct jobs customers hire the category to perform. Use site-search logs, customer-service transcripts, product reviews, sales calls, returns reasons, and keyword research to identify real constraints and vocabulary.
| Prompt class | Example | Purpose |
|---|---|---|
| Category discovery | What are the best mineral sunscreens for daily use? | Measures broad category salience |
| Constraint-led | Recommend a fragrance-free mineral sunscreen under $30 that does not leave a white cast. | Tests structured product facts and hard filters |
| Use-case | What sunscreen should I pack for a humid week of hiking? | Tests problem-to-product reasoning |
| Comparison | Compare Product A with Product B for sensitive skin. | Tests factual differentiation and evidence |
| Audience-led | Best mineral sunscreen for a runner with sensitive skin | Tests audience and situational fit |
| Merchant-led | Where can I buy a qualifying sunscreen with delivery by Friday and free returns? | Tests offer, availability, shipping, and policy data |
For each important intent, write two or three semantically equivalent variants. Preserve the same hard constraints while changing ordinary customer language, word order, and the degree of explicitness. Avoid inserting your brand into discovery prompts unless you are testing brand knowledge specifically.
Freeze the prompt set before the run begins. If an answer suggests a clever new prompt, save it for the next wave rather than adding it halfway through and creating an unbalanced sample.
Step 3: Choose the test matrix and sample size
A full factorial design grows quickly. Four assistants × 12 prompts × two account states × two markets × ten repeats equals 1,920 runs. Most teams do not need to start there. Use a two-stage design.
Stage A: Screening audit
Run 12 to 20 prompts across three or four assistants, using one clean account state and the brand's primary market. Repeat every exact condition five times. This identifies prompts and platforms with obvious absence, dominance, or volatility.
Stage B: Focused audit
Select the four to eight commercially important prompts from Stage A. Repeat each condition at least 20 times, then add relevant account and geography comparisons. Thirty or more repeats per condition are preferable when a result will drive a material budget or public claim.
Five or ten runs are useful for finding large problems, but they are not precise estimates. If a product appears in five of ten runs, the observed inclusion rate is 50%, yet the plausible range around the underlying rate remains wide. More repeats narrow that uncertainty. For reporting proportions, use a 95% Wilson confidence interval rather than presenting the observed percentage as exact truth.
| Repeats per exact condition | Best use | Do not use it for |
|---|---|---|
| 5 | Fast smoke test and workflow debugging | Performance claims or small comparisons |
| 10 | Directional baseline and obvious instability | Declaring a 10-point difference meaningful |
| 20–30 | Operational decisions and before/after comparisons | Fine-grained causal claims without controls |
| 50+ | High-value categories, narrow intervals, subgroup analysis | A substitute for representative prompts |
Step 4: Standardize how every run is executed
Reproducibility depends more on discipline than software. Write a runbook and follow it exactly.
- Record the environment. Capture assistant name, displayed model or mode, browsing/shopping mode, date, time zone, locale, device type, account state, and any memory setting visible to the tester.
- Start from the defined state. Use a new conversation for independent runs. Clear context or use a clean profile when the platform permits it. Do not assume incognito mode removes server-side personalization.
- Submit the frozen prompt verbatim. Do not correct spelling, add a follow-up, or click a suggested chip unless that interaction is part of a separate conversational test.
- Save the complete answer. Preserve text, product cards, rank/order, citations, merchant links, prices, and a screenshot or export. A summary alone cannot be audited later.
- Apply the coding rules. Two reviewers should independently code a sample of runs before full collection, resolve disagreements, and document edge cases.
- Log failures. Timeouts, refusals, empty results, and broken product cards are outcomes, not records to quietly delete. Mark whether a rerun was attempted.
Keep Independent and Conversational Tests Separate
An independent-run test asks whether the same starting condition produces the same answer. A conversational test asks how clarification and follow-up change the answer. Both matter, but combining them destroys interpretability. Store them as separate test suites.
The data sheet: one row per recommendation
Store run-level metadata in one table and recommendation-level outputs in another, linked by a unique run ID. A response with five recommended products should produce one run record and five recommendation records.
Run table
| Field | Example | Why it matters |
|---|---|---|
| run_id | US-CLEAN-P07-GEM-014 | Stable join key |
| timestamp_utc | 2026-09-20T15:12:04Z | Detects temporal drift |
| assistant / model / mode | Platform X / displayed model / shopping | Defines the tested surface |
| prompt_id / exact_prompt | P07 / frozen text | Prevents accidental prompt drift |
| prompt_class | constraint-led | Supports intent-level analysis |
| market / locale / currency | US / en-US / USD | Captures geographic context |
| account_state | clean, signed-out | Captures personalization condition |
| run_status | valid, timeout, refusal, tool error | Keeps failure rates visible |
| raw_output_path | Evidence file or archive URL | Allows later verification |
Recommendation table
| Field | Definition |
|---|---|
| run_id | Parent run identifier |
| rank | Order first presented to the shopper |
| brand / product / variant | Normalized entity plus verbatim displayed name |
| merchant / destination URL | Where the user is sent, not merely the manufacturer mentioned |
| price / availability | Displayed values and whether they matched the destination |
| hard_constraint_pass | Yes, no, or unknown for each required condition |
| claim_accuracy | Verified, contradicted, unsupported, or not applicable |
| citation URLs | Every source exposed in the answer |
| rationale theme | Price, feature, review, reputation, policy, sustainability, or other coded reason |
Create a versioned product truth set before scoring accuracy. It should contain current specifications, compatible uses, exclusions, price, availability, shipping, returns, warranty, and supporting URLs. Freeze a timestamped copy for each audit wave so a later catalog update does not rewrite the ground truth.
The metrics that matter
1. Inclusion rate
Inclusion rate = valid runs containing the brand or product ÷ all valid runs in the condition. Report brand-level and product-level rates separately. A brand mention with no qualifying product is not equivalent to a specific purchasable recommendation.
2. First-choice rate and mean rank
First-choice rate measures how often the product is presented first or explicitly labeled the best choice. Mean rank describes prominence when it appears. Because some answers are unordered, define the ranking rule before coding; otherwise use "included, unordered" rather than inventing a position.
3. Set stability
For every pair of repeated runs, calculate the Jaccard similarity of the recommended product sets: the number of products appearing in both sets divided by the number appearing in either set. Average the pairwise values. A score near 1 means the same shortlist recurs; a score near 0 means the consideration set churns.
4. Winner concentration
Calculate the share of runs captured by the most frequently selected first choice. A 70% winner concentration means one product leads seven of ten valid runs. Also report the distribution of winners; a dominant leader and a two-product coin flip can have similar inclusion rates but very different competitive implications.
5. Prompt sensitivity
Within a family of equivalent prompts, subtract the lowest product inclusion rate from the highest. A 55% rate for one wording and 15% for another produces a 40-point sensitivity gap. Large gaps often indicate that product language or third-party evidence aligns with one vocabulary but not its synonyms.
6. Platform and geography spread
Calculate the same max-minus-min gap across assistants and markets. Keep the denominators and conditions identical. A product may be consistently visible in one assistant because its preferred sources or merchant partners differ, while another surface cannot verify local availability.
7. Constraint pass rate
Constraint pass rate = recommendations satisfying every hard requirement ÷ recommendations evaluated. Track "unknown" separately. Treating missing evidence as a pass rewards ambiguity.
8. Claim and citation quality
Report the share of material product claims that are verified, contradicted, unsupported, or stale. Also measure citation coverage: the proportion of recommendations for which the assistant exposes at least one usable supporting source. High inclusion with poor factual support is a reputational risk, not a clean visibility win.
9. Merchant capture rate
A model may recommend your product but route the transaction to a marketplace. Merchant capture rate measures the share of your product recommendations that link to your owned store or preferred partner. This separates product visibility from channel ownership.
How to read confidence intervals without pretending the system is static
A confidence interval describes sampling uncertainty within your defined test; it does not account for every future model or index update. Use it to avoid overreacting to small differences. If two observed inclusion rates have wide, heavily overlapping intervals, describe the result as inconclusive rather than declaring a winner.
For a quick operational calculation, use a Wilson interval for each proportion. Most analytics tools can compute it from successes and total valid runs. Always publish the numerator and denominator beside the percentage—for example, "18 of 30 runs, 60%; 95% Wilson interval approximately 42%–75%." That is more honest than "the brand has 60% AI visibility."
For before-and-after tests, keep prompts and conditions paired wherever possible. Compare the same prompt, platform, market, and account state in both waves. If the system changed between waves, state that limitation. Statistical significance cannot turn an uncontrolled platform change into proof that your page edit caused the outcome.
| Pattern | Interpretation | Recommended action |
|---|---|---|
| High inclusion, high stability, high validity | Durable recommendation strength in the tested scope | Protect data quality and expand to adjacent intents |
| High inclusion, low stability | Brand is in the candidate pool but not a dependable winner | Study winning rivals, rationales, and source differences |
| Low inclusion, high stability | Consistent exclusion | Fix eligibility, availability, product facts, and authority gaps |
| High inclusion, low constraint pass | Visibility is creating bad-fit recommendations | Correct ambiguous claims and machine-readable constraints |
| Strong product visibility, low merchant capture | Demand is being routed elsewhere | Improve offer data, merchant trust, delivery, and deep links |
| Large prompt sensitivity gap | Visibility depends on wording | Cover missing customer language in structured and editorial content |
A worked example
Consider a fictional skincare brand auditing the prompt family "fragrance-free mineral sunscreen under $30 for sensitive skin." The team runs three equivalent phrasings 20 times each on three assistants in a clean US account state: 180 valid runs.
| Assistant | Inclusion | First choice | Constraint pass | Set stability |
|---|---|---|---|---|
| Assistant A | 38/60 (63%) | 19/60 (32%) | 36/38 (95%) | 0.71 |
| Assistant B | 14/60 (23%) | 4/60 (7%) | 12/14 (86%) | 0.44 |
| Assistant C | 31/60 (52%) | 11/60 (18%) | 21/31 (68%) | 0.58 |
The useful conclusion is not "the brand has 46% AI share." The result says the product is a recurring candidate, but visibility is platform-dependent and Assistant C frequently misreads at least one hard constraint. Inspection shows that one phrase—"no added fragrance"—performs materially worse than "fragrance-free," while several assistant citations point to old retailer pages that omit the current formulation.
The action plan follows the diagnosis: standardize the fragrance attribute in the feed and Product schema, publish a dated formulation FAQ with evidence, correct stale retailer listings, and seek independent reviews that use both phrases accurately. The team then reruns only the affected prompt-platform cells after the sources have been recrawled. This fictional example illustrates the method; its rates are not industry benchmarks.
Common audit failure modes
Cherry-picking favorable runs
If a result is missing from the spreadsheet, it did not happen. Predefine the number of runs and retain all valid outputs, including embarrassing ones.
Changing several variables at once
A new prompt, account, location, and model in the same comparison cannot reveal which factor mattered. Vary one dimension within each comparison block.
Confusing brand awareness with recommendation
An assistant may mention a brand in background text without presenting a product as a viable choice. Define inclusion rules that require recommendation language or placement in the actual shortlist.
Ignoring availability and merchant routing
A recommendation for an out-of-stock item or a marketplace seller may create no owned-channel value. Record offer validity and destination.
Using synthetic prompts nobody asks
Prompts written only by the marketing team often encode the product's own language. Ground the suite in customer vocabulary and retain a stable benchmark subset over time.
Scoring subjective quality without a rubric
Define hard constraints, material claims, and evidence standards before seeing outputs. For nuanced rationales, double-code a sample and report reviewer agreement.
Treating assistant brands as fixed models
Consumer interfaces can change model, retrieval, shopping, and ranking components behind the same product name. Record what the interface discloses and call the tested object a surface or configuration when the underlying model is unknown.
Automating against platform rules
Use approved APIs or permitted manual testing. Do not bypass rate limits, fabricate locations, or violate terms of service to expand the sample. A smaller compliant audit is more defensible than a large dataset collected improperly.
From diagnosis to a 90-day action plan
Days 1–30: Establish the baseline
- Select one high-value category, define the truth set, and freeze 12 to 20 prompts.
- Run the Stage A screen and identify the largest exclusion, sensitivity, accuracy, and merchant-routing gaps.
- Assign ownership across SEO/GEO, merchandising, product data, ecommerce operations, and communications.
- Fix errors that could harm shoppers immediately: false claims, unsafe recommendations, stale prices, and unavailable variants.
Days 31–60: Change the evidence
- Normalize high-impact attributes and synonyms across the product feed, PDP copy, structured data, and retailer syndication.
- Publish comparison and use-case content that answers the failed prompts directly, with explicit qualifications and sourceable evidence.
- Clarify shipping, returns, warranty, compatibility, ingredients, certifications, and exclusions in machine-readable form.
- Correct inconsistent third-party listings and pursue credible independent coverage where corroboration is weak.
Days 61–90: Retest and operationalize
- Repeat matched conditions for the affected prompt families.
- Report numerator, denominator, interval, data-quality failures, and material environment changes.
- Promote stable benchmark prompts into a monthly monitor; rotate a smaller exploratory set for emerging customer language.
- Connect recommendation exposure to AI referral traffic, assisted conversions, merchant destination, and margin without assuming last-click causality.
A practical audit scorecard
Keep the primary metrics in their natural units; do not hide them inside one number. If leadership needs a summary, use a scorecard with explicit gates:
| Gate | Question | Example internal threshold |
|---|---|---|
| Coverage | Do we appear often enough for priority prompts? | Inclusion rate at or above the category baseline |
| Reliability | Does the shortlist recur? | Set stability at or above 0.60 |
| Fit | Do recommended products meet hard constraints? | 95%+ constraint pass for ordinary products; 100% for safety-critical constraints |
| Accuracy | Are material claims verifiable and current? | No contradicted safety, compatibility, ingredient, or certification claims |
| Resilience | Does normal rephrasing preserve visibility? | Prompt sensitivity gap below 25 points |
| Commercial capture | Does visibility route to a usable offer? | Valid destination, current stock, and correct price in 95%+ of product recommendations |
These are example operating thresholds, not universal benchmarks. A medical-adjacent product, replacement part, or children's product requires stricter accuracy than a low-risk decorative item. Your standard should reflect consumer harm, product complexity, and the value of the decision.
Frequently Asked Questions
How many times should I repeat each AI shopping prompt?
Use five runs to debug the process, ten for a directional baseline, and at least 20 to 30 for a condition that will influence a meaningful decision. Report counts and confidence intervals. More runs improve precision but cannot rescue an unrepresentative prompt set.
Should every run use a new conversation?
Yes for the independent consistency test. New conversations prevent earlier answers from shaping later ones. Test multi-turn clarification separately because conversation history is the variable of interest there.
Can I compare ChatGPT, Gemini, Perplexity, Claude, and retailer assistants directly?
You can compare customer-facing outcomes for the same task, but describe the differences carefully. Their catalogs, tools, personalization, citations, and commerce integrations are not identical. The audit measures surfaces as experienced by shoppers, not a pure contest between foundation models.
What counts as a recommendation?
Define it before collection. A defensible rule requires a named product or brand to appear in an explicit shortlist, product card, or affirmative recommendation. A citation, merchant result, or incidental mention alone should be coded separately.
How often should the audit be rerun?
Run a stable core monthly for priority categories and after significant feed, content, price, availability, policy, or platform changes. Quarterly may be sufficient for slower categories. Keep timestamps because model and retrieval changes can produce drift even when your site does not change.
Does a higher inclusion rate mean our optimization caused the improvement?
Not by itself. Live assistants and the web change continuously. A matched before-and-after design strengthens the inference, especially when unchanged control products and prompts remain stable, but it does not create perfect causal attribution. Describe the change as associated with the intervention unless the design supports more.
Should sponsored products be included?
Record them, but label paid and organic placements separately whenever the interface discloses the distinction. Combining them obscures whether visibility was earned through product evidence, commerce partnerships, or media spend.
What should we do if recommendations are consistent but inaccurate?
Treat it as a priority correction. Identify the repeated claim and its likely sources, update first-party and syndicated data, contact publishers or merchants carrying the error, and preserve the evidence. Consistent misinformation can scale faster than an intermittent mistake.
The operating principle
AI recommendation visibility should be managed like any other noisy commercial system: with a frozen test set, controlled conditions, repeated observations, explicit quality gates, and an audit trail. The objective is not to force every assistant to produce the same answer. Different assistants can reasonably weight price, reputation, specifications, and sources differently.
The objective is to know whether your product is reliably eligible, accurately represented, and competitive across the situations that matter to customers. Once the team can distinguish a stable advantage from a lucky screenshot, it can invest in the product data, evidence, content, and merchant experience most likely to improve the next set of runs.
References & Further Reading
Continue Exploring
How Retailers Stay Visible When AI Shopping Agents Choose the Products
Improve the product data, trust signals, and evidence that determine recommendation eligibility.
The UCP Readiness Audit
Use a technical scoring framework to evaluate whether agents can discover, understand, and transact on your storefront.
How Retail AI Agents Discover Products
Understand how shopping agents retrieve, evaluate, and narrow products before making a recommendation.