Agentic Share of Search: How to Measure Brand Visibility in AI Shopping Results
A rigorous, repeatable framework for measuring how often, how prominently, and how accurately your brand and products appear across AI shopping results—with prompt design, scoring formulas, volatility controls, and an audit template.
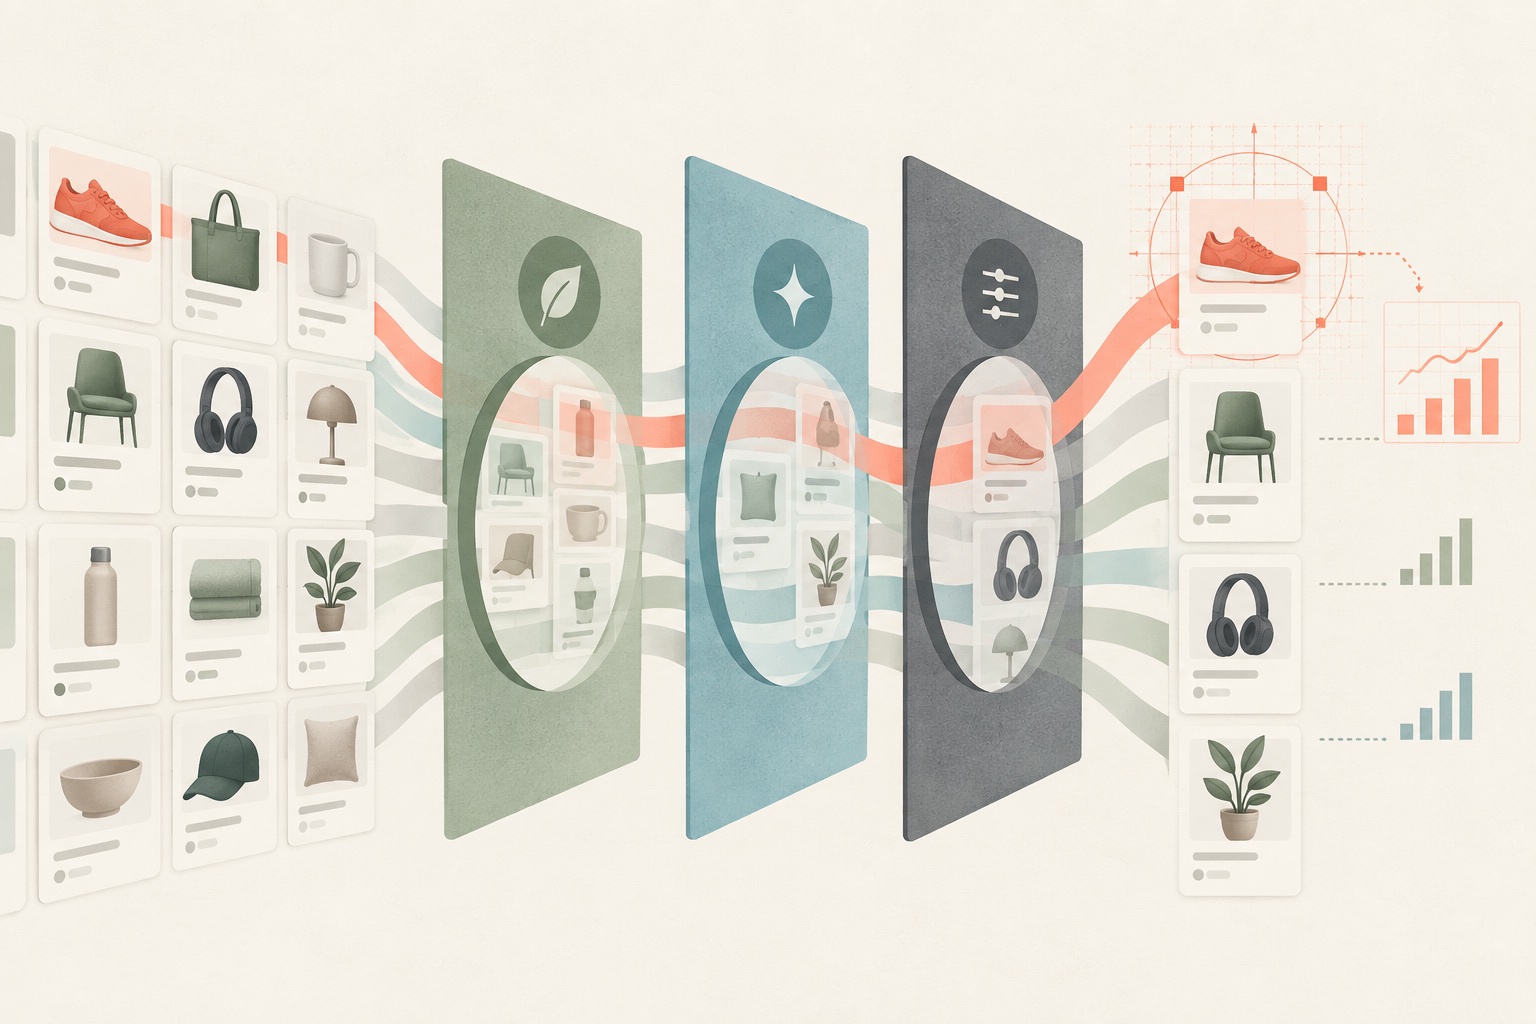
A shopper asks an AI assistant for the best carry-on for a two-week trip. Three brands appear. One is named first, linked to a specific product, and described with current price and warranty details. Another is mentioned without a link. Your brand does not appear at all. A conventional rank tracker cannot explain this result, because an AI answer is not a page of ten stable blue links. It is a generated recommendation assembled from a changing mix of models, sources, product feeds, context, and language.
That does not make AI shopping visibility immeasurable. It makes the measurement design more important. Agentic share of search is a practical way to quantify how often, how prominently, and how accurately a brand or product appears when AI systems answer commercially relevant prompts. Done well, it turns scattered screenshots into a repeatable competitive signal. Done badly, it produces a precise-looking number that changes with every prompt rewrite.
The working definition
Agentic share of search is a brand's weighted share of eligible recommendations across a controlled panel of shopping prompts, platforms, markets, and repeated runs. It is not the same as AI referral traffic, sentiment, citation share, or sales. Those are adjacent measures and should be reported separately.
The idea is moving from theory into practice. A September 2026 research prototype introduced Agentic Share-of-Search as a seller-side decision target and used query agents across AI platforms to measure visibility and diagnose merchandising changes. Its 100-trial ablation study was explicitly framed as a feasibility test, not a universal benchmark. Separately, NIQ and Similarweb announced a measurement approach spanning consumer intent, agentic shelf visibility, content readiness, AI-driven traffic, and conversion. The direction is clear: companies need to connect what appears inside AI answers with what happens commercially, without pretending those are the same metric.
Why Traditional Share of Search Is Not Enough
In traditional search, a rank can usually be tied to a query, location, device, and timestamp. Generative systems add several sources of variation. The same prompt can return different brands on consecutive runs. A follow-up question can replace the original shortlist. A brand may appear in prose but not in a product module. A cited retailer may receive the click even though the manufacturer earned the recommendation. Logged-in history, location, model version, browsing mode, inventory, and sponsored placement can all affect the answer.
| Signal | What it answers | What it does not prove |
|---|---|---|
| Brand mention | Was the brand named anywhere? | That it was recommended or linked |
| Recommendation | Was it presented as a suitable choice? | That the shopper could buy the right item |
| Product appearance | Was a specific SKU or product family surfaced? | That the details were accurate or current |
| Citation or merchant link | Which source or seller received attribution? | That the brand originated the information |
| AI referral | Did a measurable visit arrive from an AI platform? | How many no-click recommendations influenced demand |
| Conversion or sale | Did an observed commercial outcome occur? | That AI caused the outcome without incrementality testing |
The first discipline is to resist collapsing every signal into one score. Use a headline index for executive reporting, but keep the component measures visible. If recommendation share rises while factual accuracy falls, the business has not simply improved.
Step 1: Define the Decision Before the Metric
Start with the decision the audit must support. A category team may need to know which use cases the brand loses. A merchandising team may need to identify missing attributes. A communications team may want to understand which sources shape AI answers. A growth team may need to connect visibility with qualified traffic. Those questions require overlapping data, but not identical samples.
Write a one-sentence charter before collecting prompts: We will measure whether Brand X and its priority products are recommended accurately for non-branded running-shoe needs in the United States across five AI discovery surfaces, and use the result to prioritize product-content and authority improvements.
Lock five scope variables
- Entity: brand, product family, SKU, retailer, or marketplace seller. Keep separate identifiers for each.
- Category: define the competitive set at the level shoppers use, not only the internal taxonomy.
- Market: country, language, currency, and delivery region.
- Surface: the exact AI product and mode tested, including whether web browsing or shopping modules are active.
- Outcome: awareness, consideration, product selection, merchant selection, or transaction readiness.
Do not silently change scope between waves. A result from a general chatbot, an embedded retail assistant, and a marketplace shopping agent may all be useful, but averaging them without labels destroys the diagnostic value.
Step 2: Build a Prompt Set That Represents Demand
The prompt set is the equivalent of the keyword universe in SEO, but natural-language shopping demand is broader and more conditional. Do not begin with prompts your brand is already designed to win. Begin with the jobs shoppers are trying to complete.
| Prompt family | Example | Why include it |
|---|---|---|
| Category discovery | What are the best carry-on suitcases? | Measures broad consideration |
| Need-state | A durable carry-on for weekly business travel | Tests use-case fit |
| Constraint | Best carry-on under $250 that fits US overhead bins | Tests price and specification eligibility |
| Attribute | Lightest expandable hard-shell carry-on | Tests structured product detail |
| Comparison | Brand A versus Brand B for international travel | Measures competitive positioning |
| Risk or objection | Which carry-on has the best warranty and easiest returns? | Tests policies and trust signals |
| Audience | Carry-on for a petite traveler who cannot lift much | Tests suitability and inclusion |
| Transactional | Find an in-stock blue carry-on delivered to Boston by Friday | Tests live offer and fulfillment data |
| Branded validation | Is Brand X's Model Y worth it? | Tests accuracy after awareness already exists |
Use three sources for prompts
- Observed demand: site search, customer-service transcripts, paid-search queries, retailer questions, reviews, and sales-team notes.
- Category structure: product attributes, price bands, audiences, occasions, compatibility requirements, and common objections.
- Exploratory language: interviews with customers who describe the need without using the brand's vocabulary.
Keep branded and non-branded prompts in separate reporting groups. Branded prompts measure whether the system represents known demand correctly; they should not inflate a score meant to represent competitive discovery.
Weight prompts without manufacturing a win
Assign each prompt a weight before testing. Use observed demand where reliable. Where AI-specific demand volumes are unavailable, combine category-search demand, first-party frequency, strategic revenue, and expert judgment. Normalize all prompt weights so they sum to 1. Record the rationale and freeze weights for the reporting period.
Prompt weight = normalized(demand proxy × commercial relevance × strategic priority)Avoid false precision. A three-level scheme—high, medium, low—converted to weights of 3, 2, and 1 is often more defensible than invented monthly prompt volumes.
Step 3: Design the Test Panel for Repeatability
A prompt is not a measurement unit. The unit is a prompt-platform-market-run observation. For every observation, record enough context to reproduce it:
- Prompt ID and exact wording
- Platform, product surface, model or mode when disclosed
- Date, time, country, language, currency, and device class
- Logged-in or clean-session state and personalization status
- Browsing, shopping, or product-card features observed
- Full answer, screenshot, citations, links, product cards, and follow-up steps
A practical minimum sample
For a directional category audit, start with 50–100 prompts, three to five relevant platforms, and three independent runs per prompt-platform pair. One hundred prompts across four platforms and three runs produces 1,200 observations. That is large enough to expose instability without becoming an unmanageable research program. High-value or highly volatile prompts may justify five to ten runs.
Run comparisons in matched blocks: test all brands through the same prompt set, platform configuration, geography, and collection window. Randomize prompt order where practical. Start fresh sessions unless personalization is the object of the study. Never compare your clean-session results with a competitor set collected from a heavily personalized account.
Two panels are better than one
Benchmark panel: fixed prompts and settings retained over time. This reveals genuine trend movement.
Discovery panel: rotating prompts that capture new products, seasonal needs, emerging language, and platform capabilities. This prevents the benchmark from becoming stale.
Step 4: Code Each Answer at Four Levels
Store the raw output, then code it using a stable rubric. Human review remains valuable because an exact brand-name match can still be a negative mention, and a product card may be present even when the prose ignores it.
- Brand level: mentioned, recommended, first recommended, compared, discouraged, or absent.
- Product level: exact SKU, product family, wrong or ambiguous product, variant, price, availability, and merchant.
- Evidence level: brand-owned citation, retailer citation, editorial source, user-generated source, uncited claim, or broken link.
- Quality level: factual accuracy, fit to stated constraints, current data, clear rationale, and transactional completeness.
Create an entity dictionary before coding: official brand names, common variants, product aliases, previous names, retailer-exclusive names, and parent-company relationships. Sample at least 10% of coded outputs for a second-reviewer check. If reviewers disagree often, refine the rubric before interpreting results.
Step 5: Calculate the Core Metrics
Report raw counts alongside percentages. Every metric should state its denominator, because “40% visibility” can mean 40% of prompts, 40% of runs, or 40% of all recommendation slots.
1. Response eligibility rate
Eligible response rate = responses containing any valid product recommendation ÷ all test runsThis separates brand failure from surface failure. If the assistant refuses, produces no products, or cannot satisfy the prompt, that observation should not automatically become a competitive loss. Report both all-run and eligible-response denominators where the difference is material.
2. Brand mention rate
Brand mention rate = eligible responses naming the brand ÷ eligible responsesUseful for awareness, but weak on its own. A brand named as an inferior alternative still counts as a mention.
3. Recommendation rate
Recommendation rate = eligible responses positively recommending the brand ÷ eligible responsesRequire explicit inclusion as a suitable option. Incidental citations, navigational mentions, and negative comparisons do not qualify.
4. Share of recommended slots
Slot share = brand recommendation slots ÷ all recommendation slots in the competitive setA slot can be a numbered-list position, a distinct product card, or an unranked shortlist entry. Define the rule once. If rank matters, apply a transparent position weight—for example 1.0 for first, 0.75 for second, 0.5 for third, and 0.25 thereafter—and report both weighted and unweighted shares.
5. First-choice share
First-choice share = eligible responses placing the brand first ÷ eligible responsesThis captures a distinction slot share can hide. A brand repeatedly included fourth has reach, but not the same decision influence as the default recommendation.
6. Citation and merchant-link share
Citation share = citations to brand-controlled URLs ÷ all relevant citations
Merchant-link share = purchasable links for the brand ÷ all purchasable links in the set
Keep these separate. A manufacturer may win the recommendation while a marketplace or retailer wins the link and customer relationship.
7. Product coverage
Priority-product coverage = priority products surfaced at least once ÷ eligible priority productsAlso report concentration: what percentage of brand recommendations go to the top one or top three products? Strong brand visibility concentrated in a discontinued hero SKU is a hidden weakness.
8. Accuracy and constraint-fit rate
Accuracy rate = verified brand/product claims that are correct ÷ verified claims reviewed
Constraint-fit rate = recommendations satisfying all hard prompt constraints ÷ recommendations reviewed
Audit price, availability, specifications, compatibility, policies, certifications, and delivery promises. Accuracy is not a visibility bonus; it is a guardrail. A prominent but wrong answer can create returns, compliance exposure, and distrust.
9. Transactional availability rate
Transactional availability = recommended products with a valid in-stock purchase path ÷ recommended productsThis reveals whether visibility can become action. Record whether the route goes to the brand, a retailer, a marketplace, or an in-interface checkout.
Step 6: Measure Volatility, Not Just the Average
AI recommendations are probabilistic. A 40% recommendation rate might mean the brand appears reliably in four of ten prompt families, or erratically across all of them. Those patterns demand different action.
Run-to-run inclusion consistency
Prompt consistency = runs containing the brand ÷ repeated runs for that promptClassify prompts as stable wins (80–100%), contested (30–79%), and stable losses (0–29%) only after enough repeats. These bands are an operating convention, not an industry law.
Recommendation-set overlap
Jaccard overlap = brands shared by two runs ÷ brands appearing in either runAverage pairwise overlap across repeated runs. A low score means the whole category is unstable; a brand's movement may reflect system variance rather than a specific merchandising change.
Wave-to-wave change
Calculate the change in each metric against the same fixed panel and include a confidence interval or bootstrap range when sample size allows. At minimum, require movement to persist across two waves before declaring a durable gain. Annotate platform launches, model changes, feed outages, promotions, inventory shocks, and major competitor activity.
A Transparent Agentic Share-of-Search Index
There is no universally accepted composite formula. The following 0–100 model is a practical management index, not a claim about an official standard:
ASoS Index =
  35% × weighted slot share
+ 25% × recommendation rate
+ 15% × first-choice share
+ 10% × brand-owned citation share
+ 10% × priority-product coverage
+  5% × transactional availability

Quality gate: publish accuracy and constraint-fit beside the index.
Do not use accuracy to compensate for absent visibility—or visibility to hide inaccuracy.
Calculate the components at observation level using prompt, platform, and market weights. Keep the weights unchanged for trend reporting. If leadership wants a different mix, show the effect of that choice and back-cast prior waves before drawing conclusions.
Illustrative scorecard
| Metric | Brand | Leader | Interpretation |
|---|---|---|---|
| Recommendation rate | 42% | 61% | Brand enters consideration, but inconsistently |
| Weighted slot share | 18% | 29% | Under-indexes on prominence |
| First-choice share | 9% | 24% | Rarely treated as the default answer |
| Brand-owned citation share | 12% | 20% | Third parties define much of the story |
| Accuracy rate | 87% | 95% | Price and warranty details need correction |
| Average set overlap | 0.46 | Category results are materially volatile | |
This table is illustrative. Its value comes from the diagnosis: the brand does not merely need “more AI visibility.” It needs evidence and merchandising strong enough to move from occasional inclusion to first-choice status, while correcting inaccurate commercial details.
Turn the Score Into a Diagnostic Workflow
A useful audit ends with hypotheses and owned actions. Segment losses by prompt family, product, platform, source type, and failure mode.
| Observed pattern | Likely investigation | Owner |
|---|---|---|
| Strong branded, weak non-branded visibility | Category authority, comparative content, third-party coverage | SEO/content/PR |
| Brand named, no specific products | Product identifiers, attribute completeness, variant mapping | Merchandising/PIM |
| Correct product, wrong price or stock | Feed freshness, offer schema, retailer synchronization | Commerce operations |
| Recommended, but competitor receives links | Merchant eligibility, direct feed access, PDP crawlability | Ecommerce/platform |
| Visibility isolated to one platform | Platform-specific sources, integrations, and coverage | Channel lead |
| High mention, low first-choice share | Differentiation, proof, reviews, price-value positioning | Brand/product marketing |
| Sharp movement with low overlap | Model variance before assuming business impact | Analytics |
Change one meaningful cluster at a time when possible: enrich a product family's attributes, clarify policies, publish a comparison resource, correct identifiers, or improve feed freshness. Record the intervention date and affected URLs or SKUs. Re-run the matched panel after the system has had time to recrawl or ingest the change. Visibility measurement is observational; controlled interventions make the diagnosis more credible.
The Practical Audit Template
A spreadsheet or database should contain four linked tabs or tables.
1. Prompt registry
| Required field | Example |
|---|---|
| prompt_id | LUG-NEED-014 |
| prompt_text | Durable carry-on for weekly business travel |
| family / funnel_stage | Need-state / consideration |
| brand_status | Non-branded |
| market / language | US / English |
| weight / rationale | 3 / frequent support and search theme |
| hard_constraints | Carry-on size; durable; business use |
2. Run log
Record run_id, prompt_id, platform, mode, date-time, session state, locale, raw response, screenshot path, response eligibility, and analyst. Preserve the unedited answer; extraction can be corrected later, but missing source material cannot.
3. Recommendation and citation log
Use one row per brand-product appearance: run_id, brand_id, product_id, position, recommendation status, sentiment, stated rationale, cited domain, destination URL, merchant, price, stock, and purchase-path status.
4. Verification and action log
Track each checked claim, expected value, observed value, source of truth, accuracy status, severity, probable cause, owner, intervention, target date, and retest result.
Minimum viable monthly report
- Headline ASoS Index with sample size and change versus matched prior wave
- Recommendation, first-choice, slot, citation, product coverage, accuracy, and volatility metrics
- Platform and prompt-family splits
- Top five stable wins, contested opportunities, and stable losses
- Material inaccuracies and commercial risk
- Three prioritized interventions with owners and retest dates
Cadence: Monitor Frequently, Decide Slowly
| Cadence | Purpose | Recommended scope |
|---|---|---|
| Weekly | Detect outages, broken links, material misinformation | Small sentinel set of critical prompts |
| Monthly | Operating scorecard and intervention review | Full fixed benchmark panel |
| Quarterly | Strategy, weights, competitors, commercial linkage | Benchmark plus refreshed discovery panel |
| Event-triggered | Assess a major model, product, feed, or policy change | Matched pre/post sample with annotations |
Do not optimize to every weekly fluctuation. Use the sentinel set for alerts and the larger matched panel for decisions. A dashboard without versioned prompts, sample counts, and run context invites overreaction.
Connect Visibility to Business Outcomes—Carefully
Agentic share of search measures discoverability and recommendation presence. It does not by itself prove incremental revenue. Link it to AI referral sessions, assisted conversions, retailer sales, branded-search lift, product-page engagement, and transaction data where available. Use campaign annotations and geographic or temporal tests when possible.
NIQ and Similarweb's announced framework is useful because it treats agentic shelf visibility, content readiness, traffic, and verified conversion as connected but distinct measurement areas. Follow that principle internally: build a chain of evidence rather than forcing every outcome into the visibility score.
Common Measurement Mistakes
- Testing once: one answer is an anecdote. Repeat runs and report consistency.
- Using only branded prompts: this measures recall after the shopper already knows you, not competitive discovery.
- Changing prompts every wave: trend lines become a mixture of market movement and sample redesign.
- Treating mentions as recommendations: incidental or negative appearances inflate the score.
- Ignoring the denominator: platform refusals and no-product answers can distort comparison.
- Combining platforms too early: aggregate scores can conceal a platform-specific failure or opportunity.
- Automating without quality control: name matching misses context, aliases, and incorrect product associations.
- Rewarding inaccurate visibility: recommendation reach is not success when claims, prices, or suitability are wrong.
- Claiming causality from correlation: visibility and sales can rise together because of a campaign or promotion.
- Optimizing for the test set: mimicking a frozen prompt list can improve the benchmark while failing real shoppers.
The 30-Day Implementation Plan
- Days 1–5: define the charter, entities, market, competitive set, platform panel, and data dictionary.
- Days 6–10: assemble 50–100 prompts from first-party demand and category structure; assign documented weights.
- Days 11–15: pilot ten prompts across all platforms and three repeats. Fix ambiguous coding rules before scaling.
- Days 16–20: collect the full benchmark, preserve raw outputs, and conduct secondary quality review.
- Days 21–24: calculate component metrics, volatility, platform splits, prompt-family splits, and the composite index.
- Days 25–27: verify material product claims and investigate the largest stable losses.
- Days 28–30: assign three interventions, preserve the benchmark version, and schedule the retest.
The objective is not to create a perfect universal score. It is to establish a controlled instrument that lets your team tell the difference between a real visibility problem, a product-data problem, an evidence problem, and ordinary model variance.
Frequently Asked Questions
What is agentic share of search?
Agentic share of search is a brand's weighted share of recommendations across a defined panel of AI shopping prompts, platforms, markets, and repeated runs. A sound measurement program also reports recommendation prominence, citations, specific product visibility, accuracy, and volatility.
How is it different from traditional share of search?
Traditional share of search commonly uses relatively stable query and ranking data. AI shopping answers are generated, can vary between runs, and may blend prose, citations, product cards, merchants, and checkout paths. That requires repeated tests and multiple visibility measures rather than a single rank.
How many prompts do we need?
For a directional category audit, 50–100 well-designed prompts across three to five relevant platforms with at least three runs per prompt-platform pair is a useful starting point. Narrow categories may need fewer; fragmented categories and market-level reporting need more. Coverage and repeatability matter more than an arbitrary prompt count.
Should branded prompts count toward the headline score?
Usually not for a competitive discovery score. Report branded prompts separately as an accuracy and brand-representation measure. Otherwise, a company can appear strong simply because the prompt already names it.
Can we automate the audit?
Collection, entity matching, metric calculation, and regression reporting can be automated where platform terms and access methods permit. Keep human review for ambiguous recommendations, sentiment, constraint fit, product identity, and high-risk factual claims. Preserve raw outputs so coding can be audited.
How often should agentic share of search be measured?
Use a small weekly sentinel panel for critical failures, a monthly fixed benchmark for operating decisions, and a quarterly review to refresh the discovery panel and connect visibility with commercial outcomes. Run matched event studies after major model, feed, catalog, or policy changes.
Does a higher score mean AI caused more sales?
No. It means the brand earned more or better visibility within the defined test panel. Connect visibility with referrals, assisted conversions, verified sales, and controlled incrementality tests before making a causal revenue claim.
References & Further Reading
Continue Exploring
The AI Readiness SEO Checklist
Prepare product pages, feeds, structured data, and site content for LLM discovery.
ChatGPT Product Carousels and Google Shopping SEO
Understand the product-data foundations behind visibility in conversational shopping results.
How Retail AI Agents Are Reshaping Product Discovery
A strategic guide to the changing discovery journey for ecommerce and brand leaders.